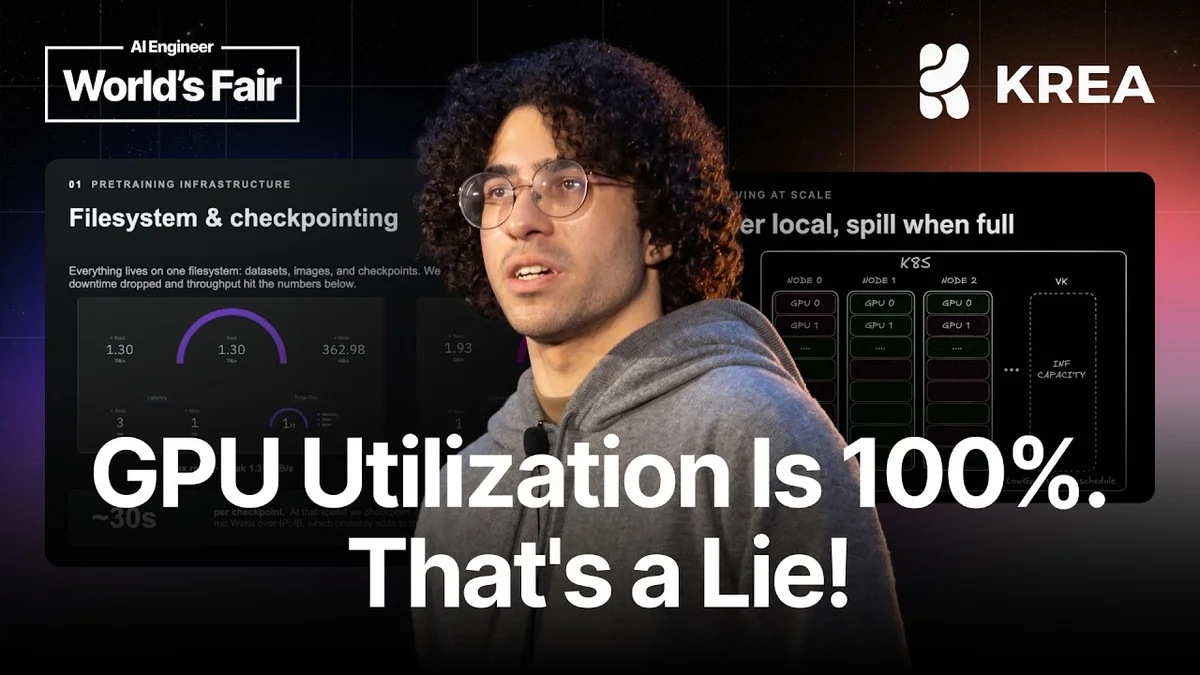
Krea.ai Details K2 Training & Serving Infrastructure

Gabriel from Krea.ai discusses the infrastructure behind K2, detailing challenges in large-scale GPU training and innovative serving solutions.

Presentation slide showing Krea.ai's K2 model details and diverse image outputs.
AI Engineer
Visual TL;DR
Krea 2 ModelCore
pre-trained, from-scratch text-to-image foundation model for diverse creative exploration
From the article 9+ mentionsGabriel from Krea.ai recently shared insights into the infrastructure powering their K2 model, detailing both the training and serving aspects.
In-house TrainingContext
From the article 8 mentionsThe model was trained entirely in-house, from scratch, without relying on any base checkpoints.
Qube ServingCore
innovative scheduling and serving infrastructure for efficient GPU inference utilization
From the article 3 mentionsFor serving and scheduling, Krea utilizes Qube, an open-source system that sits on top of the default Kubernetes scheduler.
Diverse Image StylesOutcome
From the article 2 mentionsKrea highlights the model's ability to generate diverse styles, from photorealistic to pixel art.
Training ChallengesDriver
instability grew much faster than GPU count when scaling thousands of GPUs via InfiniBand
From the article 7 mentionsThe training process for K2 involved thousands of GPUs interconnected via InfiniBand.
GPU UtilizationEffect
optimizing GPU usage for inference, addressing challenges of large-scale serving
From the article 5 mentionsHe also cautioned against relying solely on GPU utilization, advocating for tensor core utilization as a more accurate proxy for actual work being done.
Open-source K2Outcome
From the article 2 mentionsK2 is available as open-source with two checkpoints: K2 Raw for post-training and K2 Turbo, optimized for rapid image generation.
Filesystem StrategyContext
details on checkpointing and data management for large-scale distributed training
From the articleGiven the constant crashes, Krea adopted an aggressive checkpointing strategy.
Contents(5)

Gabriel from Krea.ai recently shared insights into the infrastructure powering their K2 model, detailing both the training and serving aspects. K2 is described as a pre-trained, from-scratch text-to-image foundation model designed to offer creatives tools for exploring diverse and interesting images, moving beyond what Krea perceives as "soulless" AI imagery.

Krea.ai Details K2 Training & Serving Infrastructure - AI Engineer
Krea.ai Details K2 Training & Serving Infrastructure, AI Engineer

Introducing Krea 2

K2 is available as open-source with two checkpoints: K2 Raw for post-training and K2 Turbo, optimized for rapid image generation. The model was trained entirely in-house, from scratch, without relying on any base checkpoints. Krea highlights the model's ability to generate diverse styles, from photorealistic to pixel art.

Training Infrastructure and Challenges

The training process for K2 involved thousands of GPUs interconnected via InfiniBand. Gabriel emphasized the difficulties encountered when scaling up, noting that instability increased with the number of GPUs. "Instability grew much faster than the GPU count, and much faster than published failure rates had us expect," he stated. Early experiments were more stable, but scaling to hundreds or thousands of GPUs led to more frequent crashes, often in subtle ways like NIC timeouts.

To combat these issues, Krea focused heavily on collecting metrics. Gabriel stressed the importance of monitoring GPU temperature, recommending the removal of any GPU exceeding 75-78°C to prevent throttling and instability. He also cautioned against relying solely on GPU utilization, advocating for tensor core utilization as a more accurate proxy for actual work being done.

Crucially, metrics related to InfiniBand and NVLink were highlighted as essential for diagnosing cross-node communication failures, which were a significant source of crashes. Krea had to develop custom solutions to capture these metrics, as they are not always exported by default NVIDIA tools.

Filesystem and Checkpointing Strategy

Given the constant crashes, Krea adopted an aggressive checkpointing strategy. They initially used Ceph, but found it unreliable, leading to data loss. They transitioned to Weka, a paid solution, which offered significantly improved read and write throughput (1.30 TB/s reads, 856.72 GB/s writes) and allowed for checkpoints every 20-30 minutes, producing terabytes of data quickly. This ensured that progress was not lost on training restarts.

Serving and Scheduling with Qube

For serving and scheduling, Krea utilizes Qube, an open-source system that sits on top of the default Kubernetes scheduler. Qube provides two tiers of priority: workload priority to reorder jobs and gang scheduling, essential for multi-node training. The system is designed to prioritize training jobs, even preempting inference workloads if necessary, while ensuring production services remain available.

A key aspect of their infrastructure is the ability to seamlessly shift traffic and workloads between their internal cluster and external GPU providers. This is managed using Virtual Kubelet, which presents external capacity as a virtual node within Kubernetes. This allows for efficient resource utilization, ensuring that both internal and external GPUs are leveraged effectively for training and inference without manual intervention.

GPU Utilization for Inference

Gabriel noted that for inference, diffusion models are less demanding than large language models. He humorously added that even GPUs with minor issues, like being slightly hotter than others, could still function for inference, implying a lower bar for inference hardware compared to training.

Krea is actively hiring for roles related to building and scaling such infrastructure. Interested candidates can reach out via email or check their jobs listing.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.