#GRPO
3 articles with this tag
AI Research
Small editors learn to rewrite agents at test time
Zhang et al. train a 4B proposer to edit frozen-agent harnesses from execution feedback, beating a 35B teacher on held-out Reasoning Gym families.
18 days ago
AI Research
GEPA squeezes 7x gains from three examples
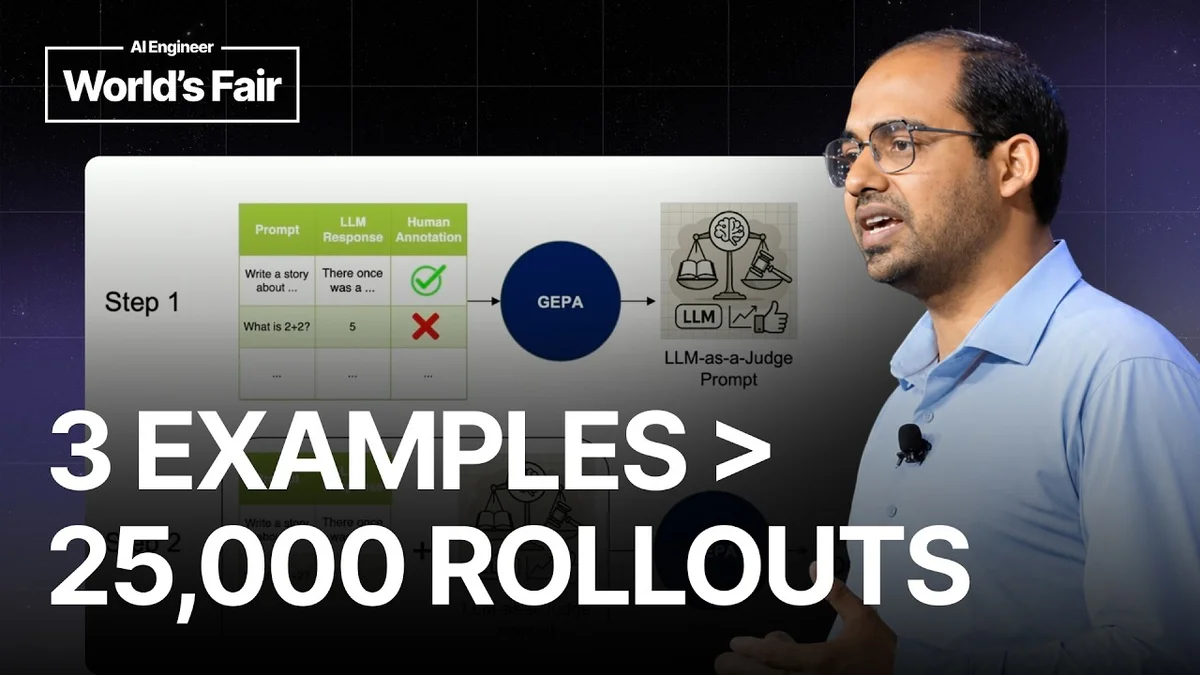
Lakshya Agrawal showed GEPA beating GRPO with 3 examples by reflecting on traces, then generalizing to Optimize Anything.
about 1 month ago

AI Figures
Liang Wenfeng's $294K DeepSeek-R1 RL Breakthrough Reached Nature
How Liang Wenfeng's DeepSeek-R1 used Group Relative Policy Optimization and pure reinforcement learning to produce emergent reasoning capabilities for $294,000 in training compute, and why the paper reached the cover of Nature.
4 months ago


