#Benchmarks
16 articles with this tag
Most read in #Benchmarks, last 30 days
Coding Agents Fail Rigorous Migration Tests
A new benchmark, SWE Refactor Bench, reveals that even frontier AI coding agents struggle to perform complete and correct whole-repository software migrations, highlighting a critical gap in current capabilities.
AI Data is the New Bottleneck, Not Models
AI experts at YC Data Club reveal data quality, not model architecture, is the key bottleneck in AI development, emphasizing the need for expert supervision and innovative data strategies.
Harvey Labs: Building AI Research on a Budget
Harvey's Gabe Pereyra shares the playbook for building a competitive AI research lab on a budget, emphasizing benchmarks, synthetic data, and leveraging the frontier ecosystem.
OpenAI Flags Major Flaws in SWE-Bench Pro
OpenAI's audit reveals approximately 30% of SWE-Bench Pro's coding tasks are flawed, prompting the company to retract its recommendation for the benchmark.
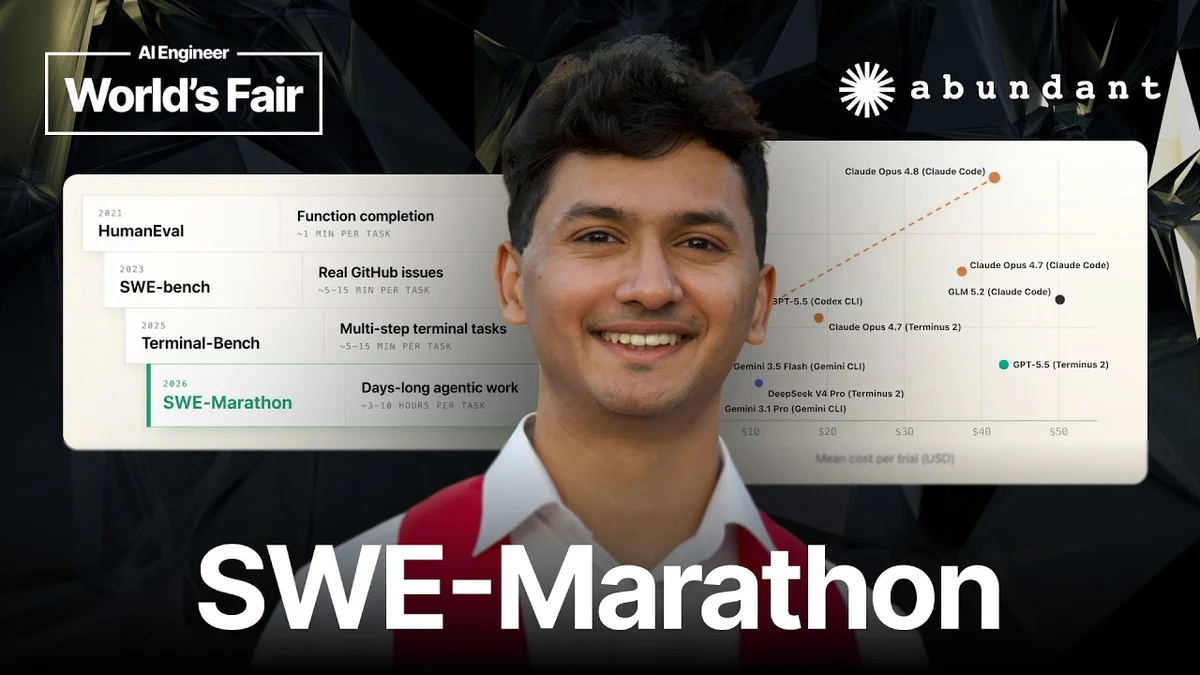
SWE-Marathon: Evaluating AI Coding Agents at Scale
Rishi Desai from Abundant AI introduces SWE-Marathon, a benchmark evaluating AI coding agents on billion-token scale tasks, revealing current limitations and the need for robust verification.

OpenAI Unveils Genebench-Pro Benchmark
OpenAI's new Genebench-Pro benchmark rigorously tests AI models on 10 complex, real-world genomics case studies.

Personalized AI Agents Now Have a Benchmark
A new iOSWorld benchmark reveals AI agents' struggles with personalized, multi-app tasks, highlighting the need for richer context and advanced reasoning capabilities.
AI Evals: Broken But Essential, Use Them Anyway
Ara Khan and Cline argue that AI evaluations, though flawed, are crucial. They outline common pitfalls and a process for iterative improvement, emphasizing honesty and nuanced assessment.
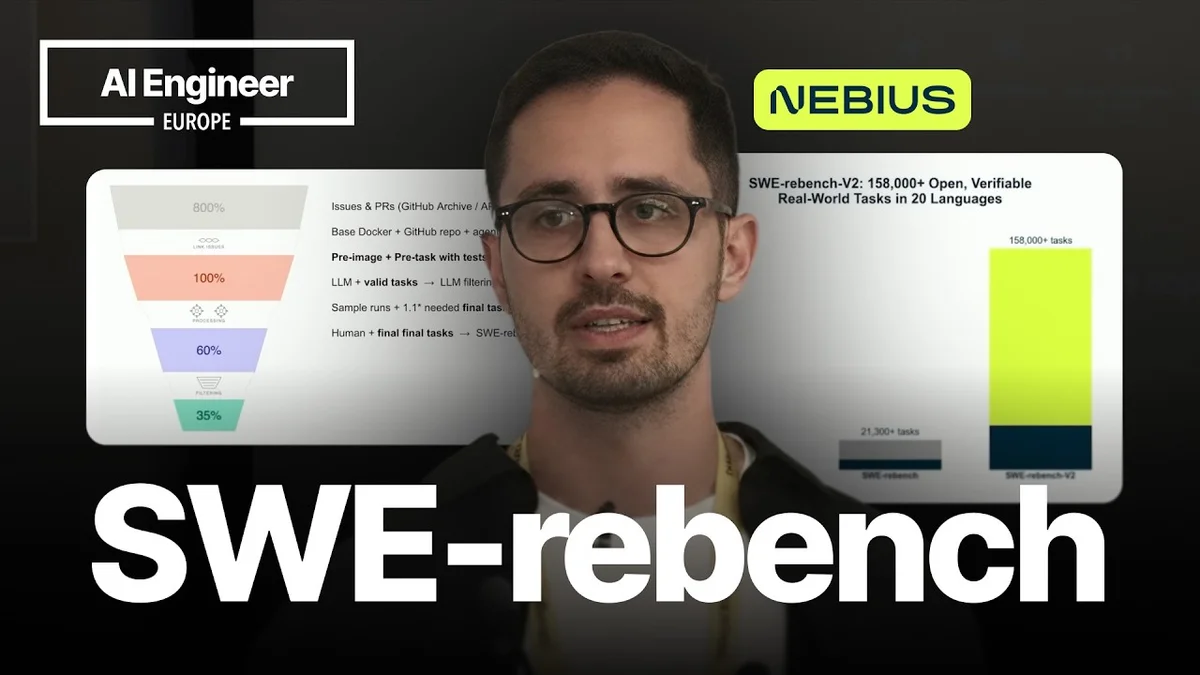
Evaluating Coding Agents: Lessons from SWE-rebench
Ibragim Badertdinov from Nebius shares key lessons from evaluating coding agents using the SWE-rebench benchmark, highlighting the importance of real-world tasks, reliable verification, and cost-effectiveness.
Active Exploration Unlocks Spatial AI
New benchmark ESI-BENCH reveals active exploration is key to embodied spatial intelligence, exposing AI's 'action blindness' and metacognitive gaps.

Unlocking AI Agents with Gym-Anything
Gym-Anything enables scalable creation of complex AI agent environments, leading to the vast CUA-World benchmark and more efficient VLM agents.
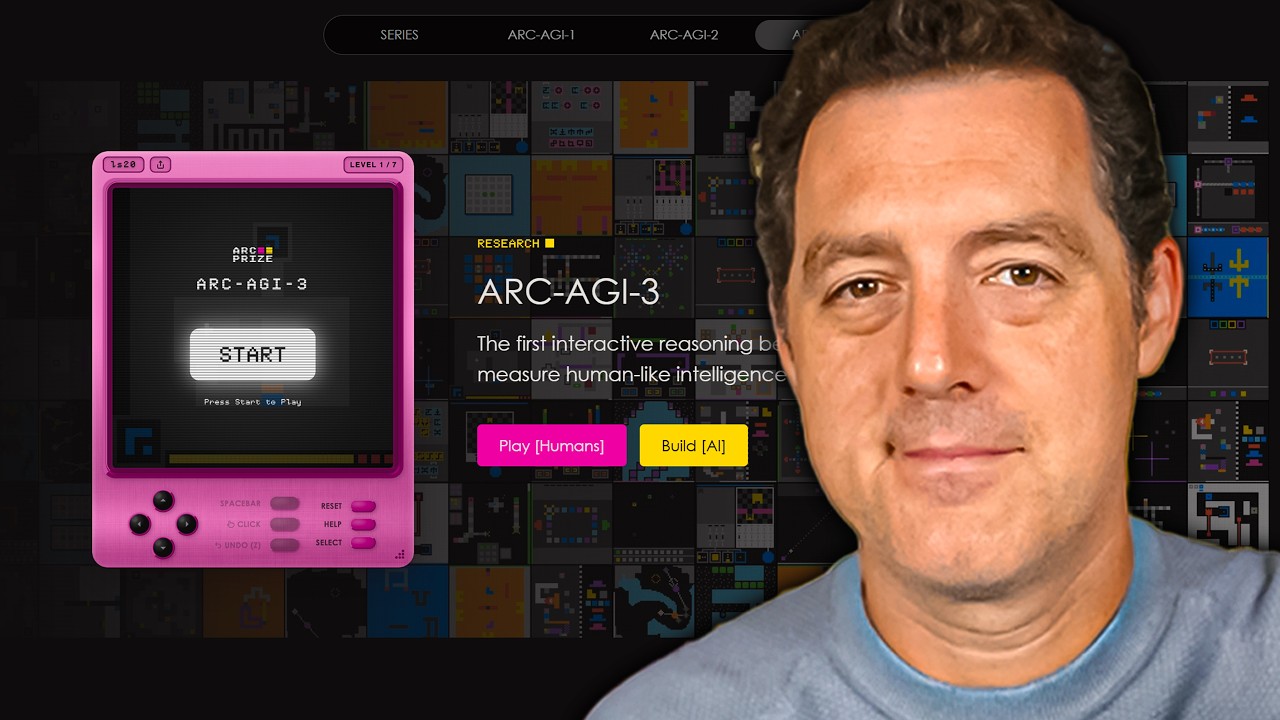
François Chollet on ARC-AGI-3: The Future of AI Reasoning
François Chollet discusses ARC-AGI-3, a new benchmark for AI reasoning, highlighting current AI's limitations and the path toward general intelligence.
AI Coding Benchmark Scores Skewed by Infrastructure
Infrastructure configuration, not just AI model prowess, can significantly skew benchmark results, complicating deployment decisions.
LMArena Series A lands $150M to standardize AI evaluation
Anthropic Wins TTFT, But OpenAI Dominates LLM Benchmarks