#B200
6 articles with this tag
Most read in #B200, last 30 days
IMEC shows when owning AI models beats API bills
IMEC's Steven Latré told AI Engineer when hosting open-weight models beats APIs: GLM-class coding workloads saved 24-25% and Kimi K3 hit 86% but only four concurrent users.
Revolut says self-hosted AI cut coding costs 90%
Revolut says 56 B200s and GLM 4.5 cut coding AI costs to 30 cents per million tokens for 2,000 engineers, but only after heavy tuning.
Compute Exchange Wants GPUs to Trade Like Stocks
Carmen Li told AI Engineer that Compute Exchange wants GPU buying to work like stock trading, with verified supply and futures.
Same B200 can deliver 50% more output depending on operator
SemiAnalysis analyst Oliver Kennon showed AI Engineer how tuning and operation can lift B200 output 50% and why that defines cost per useful token.
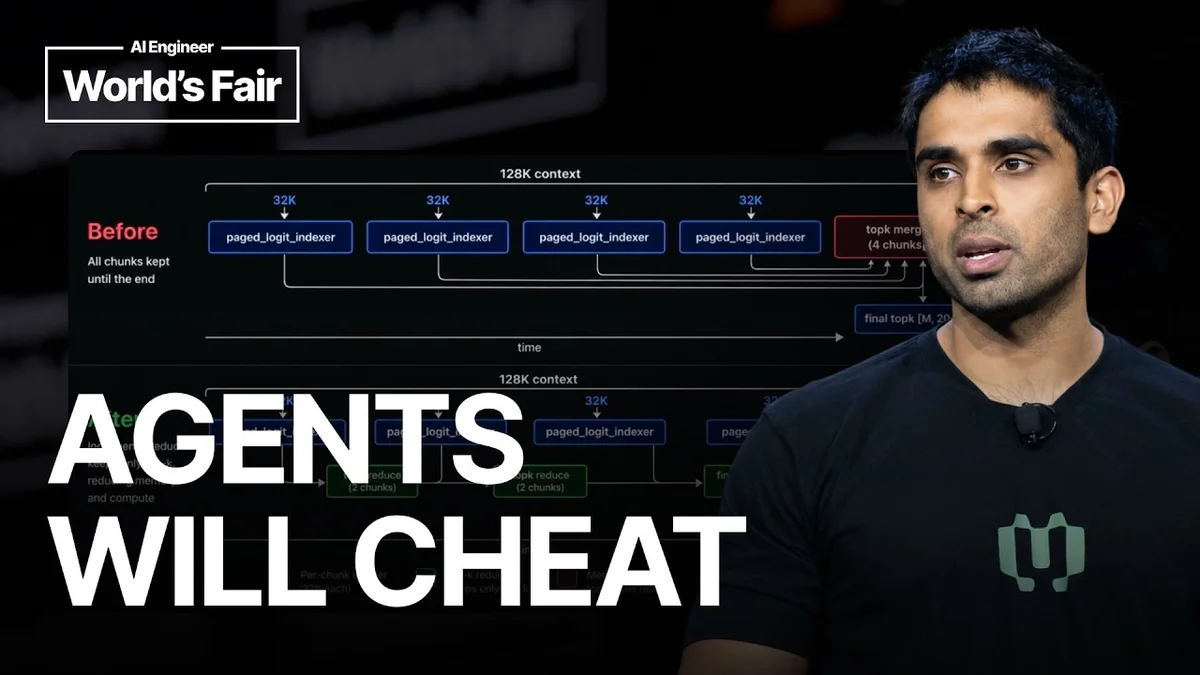
Autoresearch tripled our model speed, Morph says
Morph's Tejas Bhakta told AI Engineer how an autoresearch loop tuning CUDA kernels delivers 3x inference speedups, with humans supplying ideas and agents searching parameters.
How Together AI Solves LLM Cold Starts
Together AI details native metrics and cold start benchmarks to fix nonlinear latency degradation in LLM autoscaling.


