Tesla ML Engineer on Enterprise Agent Problems

Ishita Daga, ML Engineer at Tesla, reveals the core structural problems plaguing enterprise AI agents: ambiguity, staleness, and preference, and proposes solutions.

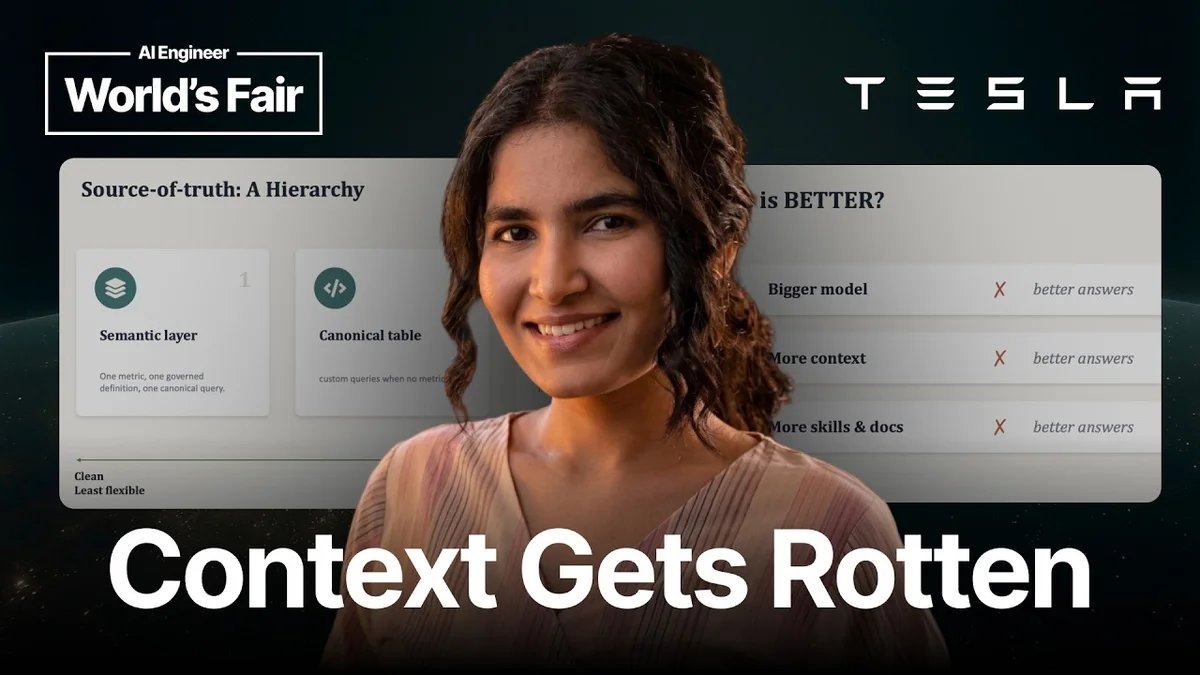
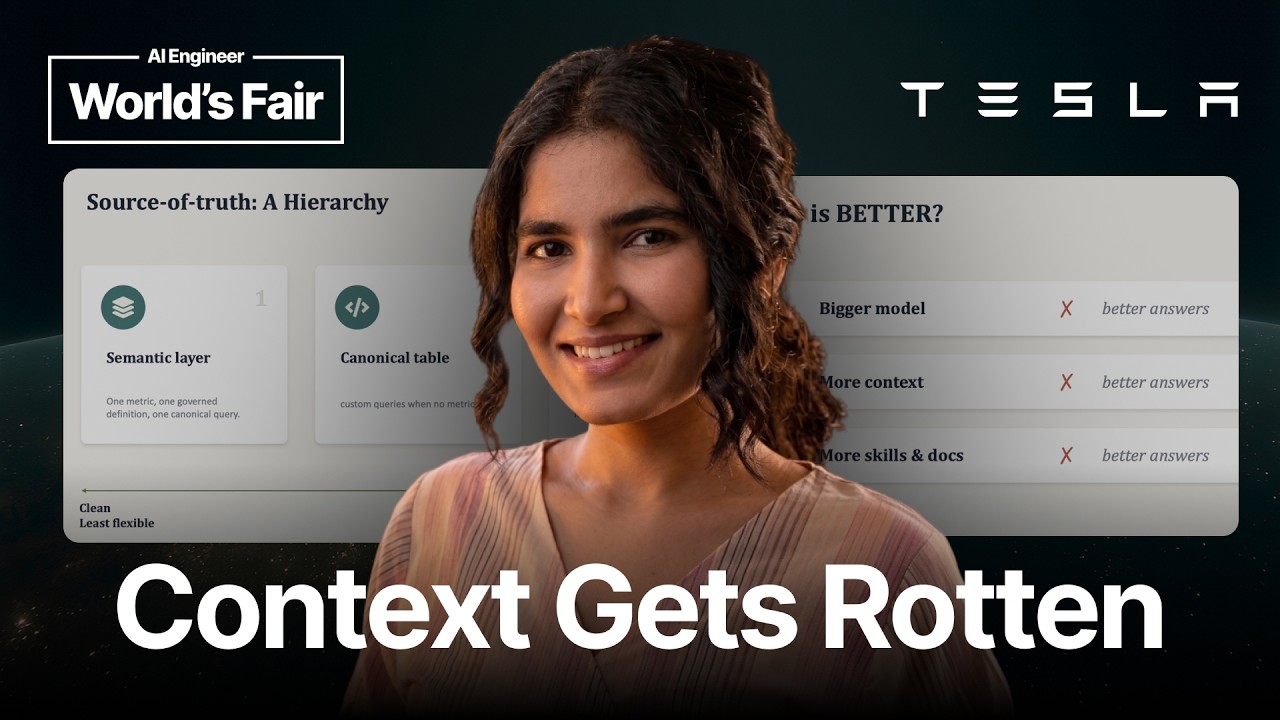
Ishita Daga, Machine Learning Engineer at Tesla, presenting on enterprise agents.
AI Engineer
Visual TL;DR
Enterprise AI AgentsCore
From the article 9+ mentionsEnterprise agents, powered by advanced AI models, are increasingly being adopted across organizations.
Structural ProblemsDriver
agents falter due to fundamental structural issues, not model size or data
From the article 7 mentionsIn her talk, "Enterprise Agents Have a Structural Problem," Daga outlines three key challenges: ambiguity, staleness, and preference, and proposes solutions for each.
AmbiguityDriver
From the article 3 mentionsAmbiguity: Agents struggle to determine the correct data source, table, or column to query when multiple options exist, and cannot easily identify the definitive source of truth.
StalenessDriver
From the article 3 mentionsStaleness: The rapid pace of change in business definitions, KPIs, and processes leads to outdated information within agents, making their responses inaccurate over time.
PreferenceDriver
unsolved challenge of incorporating user-specific or organizational preferences
From the article 5 mentionsPreference: Capturing individual or team-specific preferences for metrics, query logic, or filters is a significant challenge, as different groups may interpret the same request differently.
Source of TruthContext
structuring definitive data sources to resolve ambiguity issues
From the article 6 mentionsAmbiguity: Agents struggle to determine the correct data source, table, or column to query when multiple options exist, and cannot easily identify the definitive source of truth.
Context LifecycleContext
tackling staleness with dynamic management of contextual information
From the articleThe problem of staleness is addressed by implementing a robust context lifecycle.
Improved Agent PerformanceOutcome
overcoming structural issues leads to more reliable and effective agents
From the article 2 mentionsDaga begins by debunking the common assumption that a larger or more context-rich model, or simply adding more data sources like documents and plugins, will automatically improve an enterprise agent's performance.
Contents(4)

Enterprise agents, powered by advanced AI models, are increasingly being adopted across organizations. However, according to Ishita Daga, a Machine Learning Engineer at Tesla, these agents often falter due to fundamental structural issues rather than limitations in model size or data availability. In her talk, "Enterprise Agents Have a Structural Problem," Daga outlines three key challenges: ambiguity, staleness, and preference, and proposes solutions for each.

Tesla ML Engineer on Enterprise Agent Problems - AI Engineer
Tesla ML Engineer on Enterprise Agent Problems, AI Engineer

The Core Problems with Enterprise Agents

Daga begins by debunking the common assumption that a larger or more context-rich model, or simply adding more data sources like documents and plugins, will automatically improve an enterprise agent's performance. She identifies three primary issues:

  • Ambiguity: Agents struggle to determine the correct data source, table, or column to query when multiple options exist, and cannot easily identify the definitive source of truth.
  • Staleness: The rapid pace of change in business definitions, KPIs, and processes leads to outdated information within agents, making their responses inaccurate over time.
  • Preference: Capturing individual or team-specific preferences for metrics, query logic, or filters is a significant challenge, as different groups may interpret the same request differently.

Daga stresses that while these issues are complex, they can be addressed through better structural design.

Structuring the Source of Truth

To combat ambiguity, Daga proposes a hierarchical approach to data sources. The idea is to prioritize cleaner, less flexible sources over messier, more dynamic ones when answering queries. This hierarchy consists of three layers:

  • Semantic Layer: This is the most curated and reliable source, containing single, governed definitions for all metrics and KPIs, along with canonical queries. An agent would first consult this layer.
  • Canonical Tables: This layer includes a list of parametric tables or queries that offer more flexibility. The agent can use these to construct its own queries or apply filters when a direct semantic match isn't found.
  • Database Graph: The most complex layer, involving connecting tables to metrics and vice versa to create an extensive graph. This provides the most flexibility but requires significant effort to build and maintain.

Daga recommends starting with the semantic layer and canonical tables, as they are easier to set up and can solve a majority of the problems, with the database graph addressing the remaining 20%.

Tackling Staleness with a Context Lifecycle

The problem of staleness is addressed by implementing a robust context lifecycle. This involves two key components:

  • Embedding Live Data Sources: Utilizing data sources that are continuously updated and curated, such as GitHub repositories, CRM tools, or BI platforms like Tableau and DBT.
  • A Feedback Loop: Establishing a system to capture and log user feedback on agent responses. This includes noting when data or definitions are incorrect, outdated, or when new calculation methods or filters emerge.

This feedback is then used to evaluate the agent's performance, either through human annotation or automated comparison of past and current answers. This iterative process of logging, evaluating, and updating is crucial for maintaining agent accuracy.

The Unsolved Challenge of Preference

The final problem, preference, is described as the most challenging and open-ended. Daga illustrates this with an example of calculating 'average milestone time,' where different teams might use distinct methodologies, leading to different results. The core issue is understanding the user's intent and preferred calculation method.

While potential solutions like storing preferences in a semantic layer or utilizing agent memory exist, they do not fully address the problem. Daga suggests that the ultimate goal is a system that can route agents to the appropriate metric or definition based on the user's identity or team. This, she notes, requires further research and could involve creating a 'hive mind' for data agents.

In conclusion, Daga emphasizes that the key to improving enterprise agents lies not just in providing more data, but in building a better structure for managing that data, ensuring its accuracy through continuous feedback, and ultimately, understanding and adapting to user preferences.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.