RunPod Simplifies LLM Endpoint Deployment

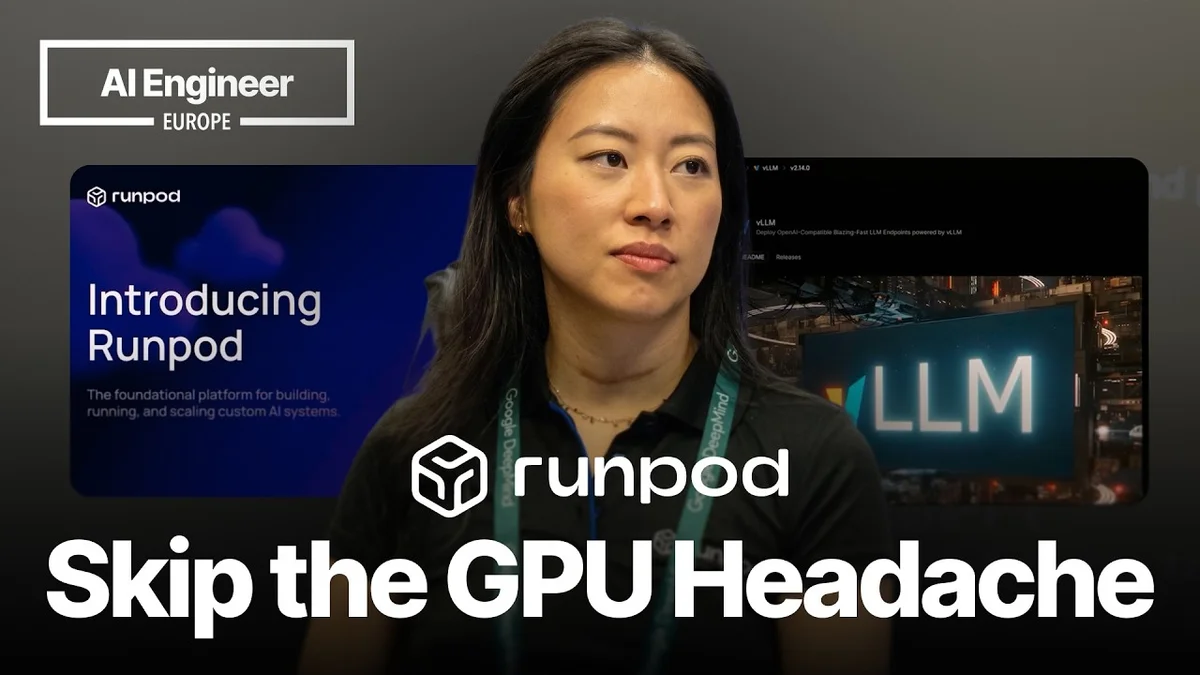
RunPod's Audry Hsu demonstrates how to deploy LLM endpoints in under 5 minutes using the platform's serverless and hub features.

Audry Hsu presenting RunPod's platform for LLM endpoint deployment.
RunPod's platform simplifies the deployment of LLM endpoints.· AI Engineer
Visual TL;DR
LLM Deployment ComplexityDriver
traditional infrastructure management and slow GPU access
RunPod PlatformCore
builders for building, running, and scaling custom AI systems
From the article 9+ mentionsAudry Hsu from RunPod presented a streamlined approach to deploying LLM endpoints, emphasizing the platform's ability to get users up and running in under five minutes.
Serverless & Hub FeaturesContext
streamlined approach to deploying LLM endpoints
Simplified AI InfrastructureOutcome
abstracts away complexities of managing AI hardware
From the article 2 mentionsThe core problem RunPod aims to solve is the time and complexity involved in managing AI infrastructure.
Observability & MetricsContext
provides insights into deployed LLM performance
From the articleRunPod emphasizes observability by providing detailed metrics on endpoint performance.
Under 5 Minute DeploymentEffect
demonstrates deploying LLM endpoints quickly
From the articleAudry Hsu from RunPod presented a streamlined approach to deploying LLM endpoints, emphasizing the platform's ability to get users up and running in under five minutes.
Focus on DevelopmentEffect
From the article 2 mentionsHsu highlighted that the platform addresses common pain points for developers, such as infrastructure management, slow GPU access, and the desire for builders to focus primarily on the development process itself rather than the underlying infrastructure.
Contents(4)

Audry Hsu from RunPod presented a streamlined approach to deploying LLM endpoints, emphasizing the platform's ability to get users up and running in under five minutes. RunPod positions itself as a foundational platform for building, running, and scaling custom AI systems. Hsu highlighted that the platform addresses common pain points for developers, such as infrastructure management, slow GPU access, and the desire for builders to focus primarily on the development process itself rather than the underlying infrastructure.

RunPod Simplifies LLM Endpoint Deployment - AI Engineer
RunPod Simplifies LLM Endpoint Deployment, AI Engineer

RunPod's Value Proposition

The core problem RunPod aims to solve is the time and complexity involved in managing AI infrastructure. Hsu noted that traditionally, developers would need to procure, configure, and maintain servers, a process that consumes valuable time and resources. This challenge is further compounded by the global GPU supply crunch, making access to necessary hardware slow and opaque. RunPod's solution abstracts away these complexities, allowing developers to focus on building and deploying their AI models.

Built by Builders, for Builders

The company's origin story is rooted in the experience of its founders. Starting in a basement in 2022, RunPod was built in public with community feedback. This approach has led to significant growth, with the company reporting $120 million in annualized recurring revenue (ARR) and over 500,000 developers using the platform by 2026. The founders' background in crypto mining, which often requires significant GPU resources, provided them with a unique understanding of the demands of scalable computing.

RunPod Offerings for LLM Deployment

RunPod offers several ways for teams to build and deploy on its platform:

  • Pods: Described as a quick and ready solution, pods offer dozens of GPU options with pay-by-the-second pricing.
  • Serverless: This option is ideal for real-time inference, variable or spikey traffic, and user-facing AI products. It features no pre-provisioning, automatic scaling, and pay-for-usage pricing.
  • Clusters: For teams requiring more intensive training, RunPod offers instant or reserved options with high-speed networking and support for frameworks like PyTorch and TensorFlow.
  • Hub: This serves as a repository for pre-built templates, enabling one-click deployments and autoscaling endpoints.

Hsu demonstrated the process of deploying an LLM using the RunPod Hub, highlighting the ease of selecting a model from Hugging Face, configuring environment variables, and deploying the endpoint. The platform provides a user-friendly interface for managing these configurations, including options for setting max model length, GPU count, and other parameters.

Observability and Metrics

RunPod emphasizes observability by providing detailed metrics on endpoint performance. Users can monitor requests, completed tasks, execution times, and delay times. This data allows developers to understand the performance of their deployed models and optimize them accordingly. The platform also offers logging and monitoring tools to help troubleshoot any issues that may arise.

The presentation concluded with a showcase of the RunPod platform's capabilities, demonstrating how quickly an LLM endpoint could be deployed and made ready for requests. The emphasis was on the platform's user-centric design, aiming to simplify the complex process of AI deployment for developers across various industries.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.