The decade-long anomaly of shallow reinforcement learning networks has finally been broken. The conventional wisdom, that deep networks inherently fail in RL, was challenged and overturned by a team from Princeton that successfully scaled models to 1,000 layers, a feat previously thought impossible. This breakthrough, which earned the team the Best Paper award at NeurIPS 2025, represents a fundamental paradigm shift that promises to accelerate the capabilities of autonomous systems.
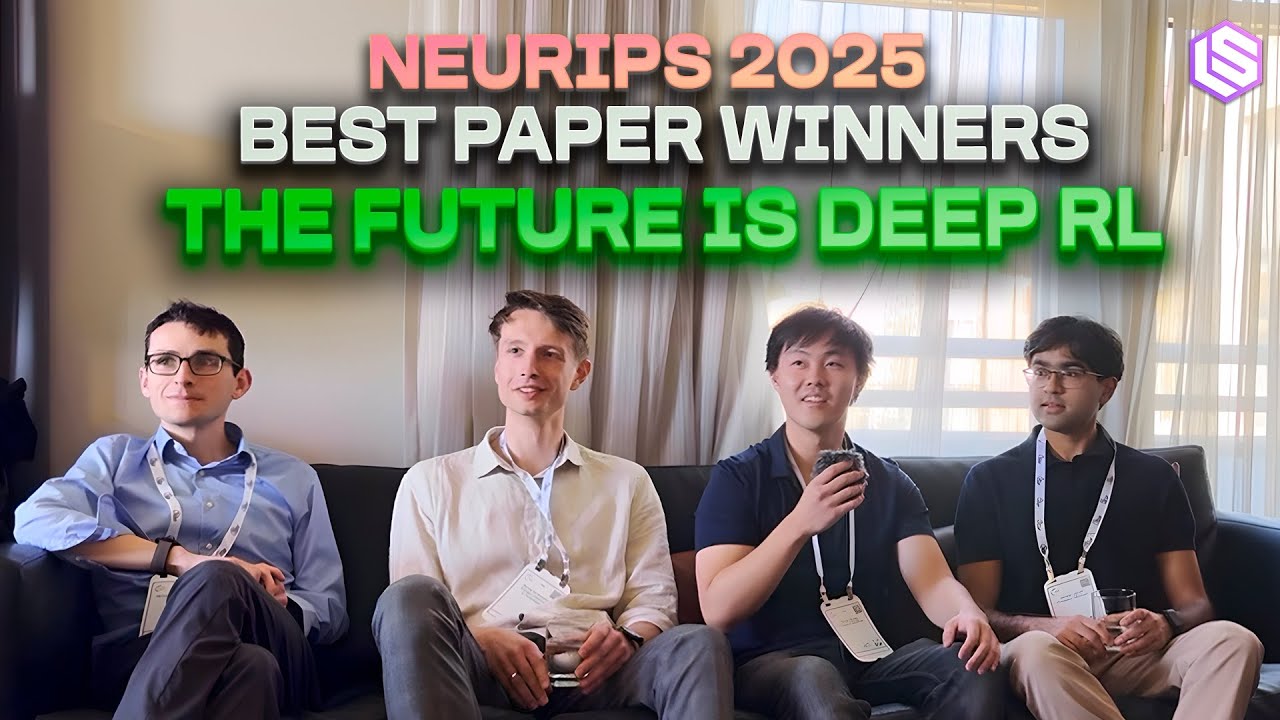
Kevin Wang, Ishaan Javali, Michał Bortkiewicz, and their advisor Benjamin Eysenbach spoke with Swyx of Latent Space at NeurIPS 2025 about their award-winning work, "1000 Layer Networks for Self-Supervised RL," detailing how they achieved massive scaling by fundamentally rethinking the core objective function. For years, deep RL models stagnated at two or three layers, an anomaly compared to the revolution seen in vision and language models. Eysenbach noted that he was "kind of skeptical it was going to work" when the students proposed pushing depth.
The key barrier, the team discovered, was not depth itself, but the traditional value-based objective function. Calculating temporal difference (TD) errors is prone to noisy, spurious, and biased signals that degrade performance as networks deepen. The Princeton team shifted the learning burden away from regression toward classification. As Kevin Wang explained, they moved from "regressing to like TD errors... to fundamentally like a classification problem." This self-supervised approach trains the network to learn representations where states along the same trajectory are pushed together, while states along different trajectories are pushed apart, proving vastly more stable under scale.
The scalability was unlocked by incorporating architectural choices proven in other domains, specifically residual connections and layer normalization, which mitigate vanishing gradients. This architectural robustness allowed them to prove that scaling depth is far more parameter-efficient than scaling width, growing parameters linearly versus quadratically for the same performance gains.
Achieving massive depth also revealed a non-linear scaling phenomenon the team dubbed "critical depth." Performance gains were not incremental; they multiplied significantly once the models crossed a threshold of around 15 million transitions and possessed the correct architectural components. This research was only feasible due to modern infrastructure, specifically, the use of JAX and GPU-accelerated environments that allowed them to collect "hundreds of millions of times of the data within just a few hours," enabling the data abundance necessary for deep networks to truly pay off.