


IBM's latest iteration of its Granite models, Granite 4.0, is poised to reshape the enterprise AI landscape by delivering superior performance, unprecedented efficiency, and cost-effectiveness through a groundbreaking hybrid architecture. This new family of small language models challenges the conventional wisdom that larger models inherently equate to better results, demonstrating that strategic architectural innovation can unlock significant capabilities within a more compact footprint.
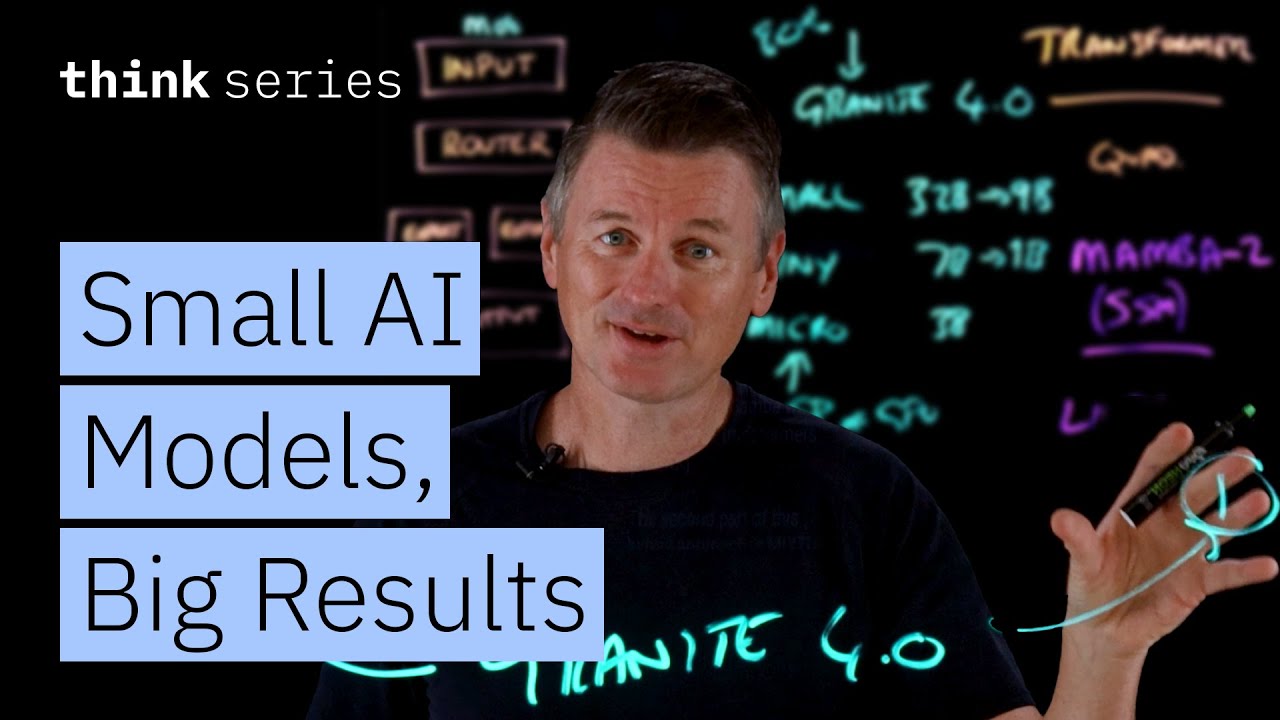
Martin Keen, a Master Inventor at IBM, elaborated on the intricacies and advantages of Granite 4.0 in a recent video, highlighting its potential to democratize advanced AI capabilities. He explained how this new generation of models is designed not merely for incremental improvements but for a fundamental shift in how businesses can leverage AI, particularly in resource-constrained environments or for specialized tasks.
A core insight into Granite 4.0's prowess lies in its remarkable efficiency. Keen emphasized, "These models, they deliver higher performance, faster speeds, and significantly lower operational costs compared to similar models, including previous Granite models, but also compared to much larger models as well." This is a crucial differentiator for enterprises grappling with the substantial computational and financial overhead typically associated with large language models. The Granite 4.0 family includes "Small," "Tiny," and "Micro" models, each tailored for specific deployment scenarios. The Micro model, for instance, requires only about 10GB of GPU memory to run, a stark contrast to comparable models that often demand four to six times that amount.
The memory efficiency of these models is a game-changer. Tiny and Small Granite models significantly reduce memory requirements, sometimes by up to 80%, while maintaining high performance.
Beyond memory, Granite 4.0 excels in speed and raw performance. Most AI models tend to slow down as batch size or context length increases, but Granite 4.0's design maintains high throughput. Furthermore, these smaller models are not just competitive within their weight class; they punch well above it. Keen proudly stated, "The Small model, for example, outperforms nearly every open model on instruction following benchmarks and keeps pace even with frontier models on function calling." This capability to rival much larger, cutting-edge models on critical agentic tasks is a testament to IBM's architectural ingenuity.