Uber Optimizes Data Exports

Uber slashes data export costs by combining Hudi column stats and table sorting, preserving cloud storage tiering.

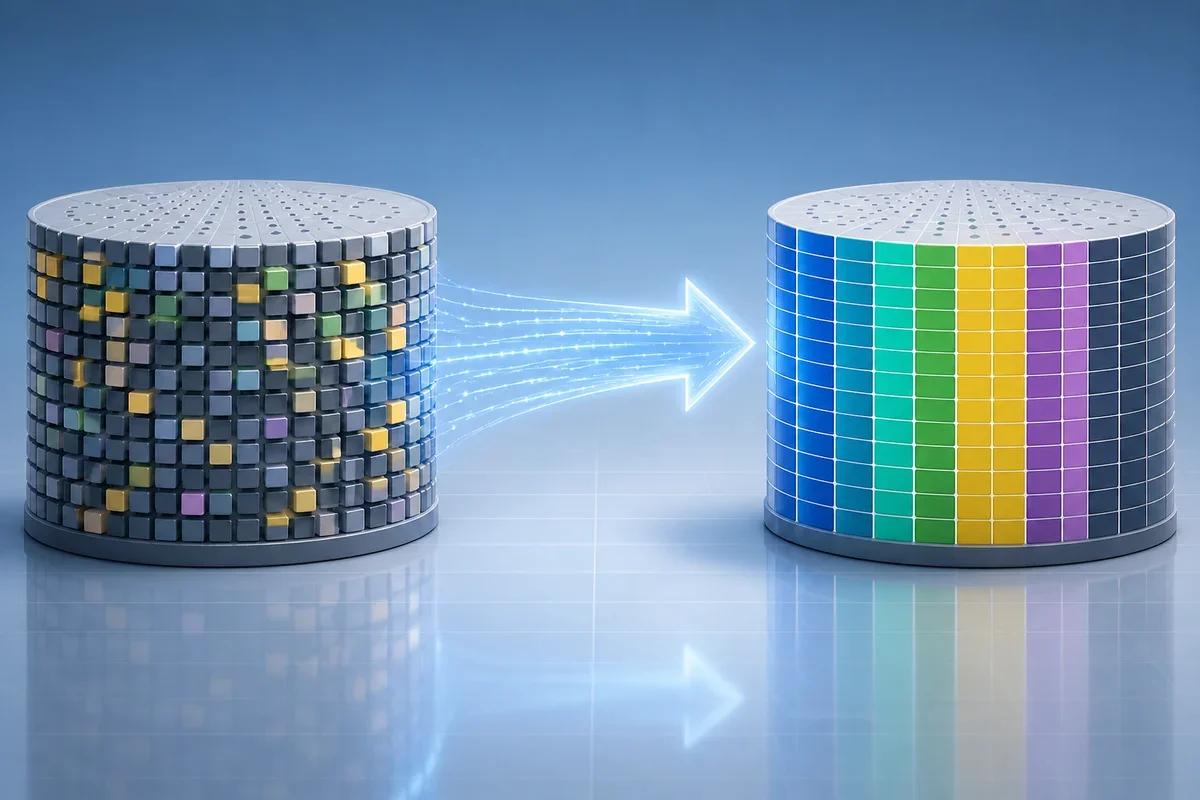
Diagram showing contrasting analytics vs export workload file scanning patterns in a Hudi table.
Uber Engineering
Visual TL;DR
High export costsDriver
DSARs and compliance requests trigger full-table scans on massive historical archives
From the article 2 mentionsConsequently, even with a secondary index, the query engine still had to inspect a substantial set of files, incurring high metadata and file-scan costs.
Hudi column statsCore
leverages Apache Hudi's built-in metadata to quickly identify relevant data files
From the article 4 mentionsColumn stats provide the mechanism for pruning, and sorting enhances its precision.
Table sortingCore
organizes data physically on disk, reducing the need to scan irrelevant blocks
From the article 7 mentionsThe solution, detailed on the Uber Engineering blog, combines Apache Hudi™ column statistics with table sorting.
Hot data problemDriver
even selective queries on cold data inflate storage, retrieval, and egress costs
From the article 2 mentionsHowever, export workloads disrupt this by keeping all data "hot" through repeated scans.
Secondary indexes failDriver
not suitable for broad historical scope and small, specific record lookups
From the articleWhile secondary indexes can identify candidate files, they proved insufficient for Uber's specific export workloads.
Winning combinationContext
Hudi column stats and table sorting work together to optimize data access
Preserves storage tieringEffect
avoids rehydrating cold data, keeping costs low on Google Cloud Storage
From the articleKey lessons from the initiative include: access patterns dictate storage costs; file layout is as important as storage tiering; metadata-driven pruning is essential; and a one-time rewrite cost can yield long-term savings.
Slashed export costsOutcome
significantly reduces storage, retrieval, and egress expenses for export workloads
From the articleUber engineers have developed a method to significantly reduce the cost of running specific data export workloads.
Contents(5)

Uber engineers have developed a method to significantly reduce the cost of running specific data export workloads. These tasks, often related to compliance or privacy requests like Data Subject Access Requests (DSARs), involve retrieving small datasets from massive historical archives. The challenge lies in the fact that even selective queries can trigger full-table scans, leading to inflated storage, retrieval, and egress costs on their Google Cloud Storage™-backed lakehouse. The solution, detailed on the Uber Engineering blog, combines Apache Hudi™ column statistics with table sorting.

Export workloads are characterized by their narrow search criteria but broad historical scope. Unlike typical analytics queries that might process large amounts of recent data, these export tasks repeatedly hunt for specific records across years of historical information. This pattern, described as finding a needle in a haystack where the haystack is the entire data table, forces systems to repeatedly access data files. This constant activity prevents cloud storage services, like Google Cloud Storage, from automatically moving less-frequently accessed data to cheaper, colder tiers. StartupHub.ai data indicates Uber scores 76/100, with a verified post-money valuation of $4K, placing it above competitors like The Bot Company (62/100) and Agility Robotics (58/100).

The Problem with Hot Data

Google Cloud Storage offers tiered storage, allowing data to move to cheaper classes like Nearline, Coldline, or Archive based on access frequency. However, export workloads disrupt this by keeping all data "hot" through repeated scans. Even reading file metadata or footers, which contain column statistics in formats like Parquet, can keep objects in the expensive Standard tier. This negates the cost-saving benefits of auto-tiering, leading to unnecessarily high storage bills. Uber's goal is to achieve a distribution closer to 60% Standard, 15% Nearline, 10% Coldline, and 15% Archive, but hot data keeps everything at 100% Standard.

Why Secondary Indexes Fell Short

The team explored Apache Hudi's secondary index feature, which is designed to accelerate queries on non-primary key columns by helping engines prune data files. While secondary indexes can identify candidate files, they proved insufficient for Uber's specific export workloads. The issue is that records for a given subject ID are often spread across a large number of files. Consequently, even with a secondary index, the query engine still had to inspect a substantial set of files, incurring high metadata and file-scan costs. The overhead of maintaining the index itself also added to the operational burden.

The Winning Combination: Column Stats and Sorting

Uber's successful approach hinges on two key components working in tandem. First, Apache Hudi maintains column-level statistics (min, max, null counts) in its metadata table, separate from the actual data files. This allows query engines to identify relevant files for a predicate without reading the Parquet data itself, drastically reducing the scan surface area. This metadata-driven pruning is crucial for keeping older data cold and preserving GCS auto-tiering benefits.

Second, table sorting is applied to the predicate columns. Since export queries are frequently driven by subject identifiers (like rider IDs), sorting clusters records for the same subject into a smaller subset of files. When combined with Hudi's column statistics, this physical clustering makes file pruning far more effective. Column stats provide the mechanism for pruning, and sorting enhances its precision. This pairing transforms broad file scans into highly targeted file selection, reducing read, shuffle, and execution times for row-level queries.

Benchmarking showed significant improvements. For instance, with 5,000 predicates, a sorted partition reduced the percentage of target files accessed from 100% in an unsorted table to a much smaller fraction. The results demonstrated substantial reductions in GCS egress, compute costs, and overall storage footprint. Optimized storage also improves compression efficiency.

Broader Applicability

This pattern of narrow, subject-oriented lookups over long historical windows is common across many industries. Finance firms need it for regulatory and audit workflows. Healthcare and life sciences require it for patient history access and compliance reviews. E-commerce uses it for fraud investigations and customer support. Ad tech relies on it for attribution and personalization, and security systems use it for investigations and access reviews. The techniques Uber developed could offer substantial cost savings and performance gains in these domains.

Next Steps and Lessons Learned

Uber plans to expand these optimizations to handle multi-column lookups, exploring techniques like Z-order curves for more complex data layouts. They are also developing an automated framework to identify these "needle-in-a-haystack" access patterns and trigger optimizations only when the return on investment is clear. Key lessons from the initiative include: access patterns dictate storage costs; file layout is as important as storage tiering; metadata-driven pruning is essential; and a one-time rewrite cost can yield long-term savings. The success highlights the importance of an end-to-end design where storage layout, metadata, and query execution align.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.