

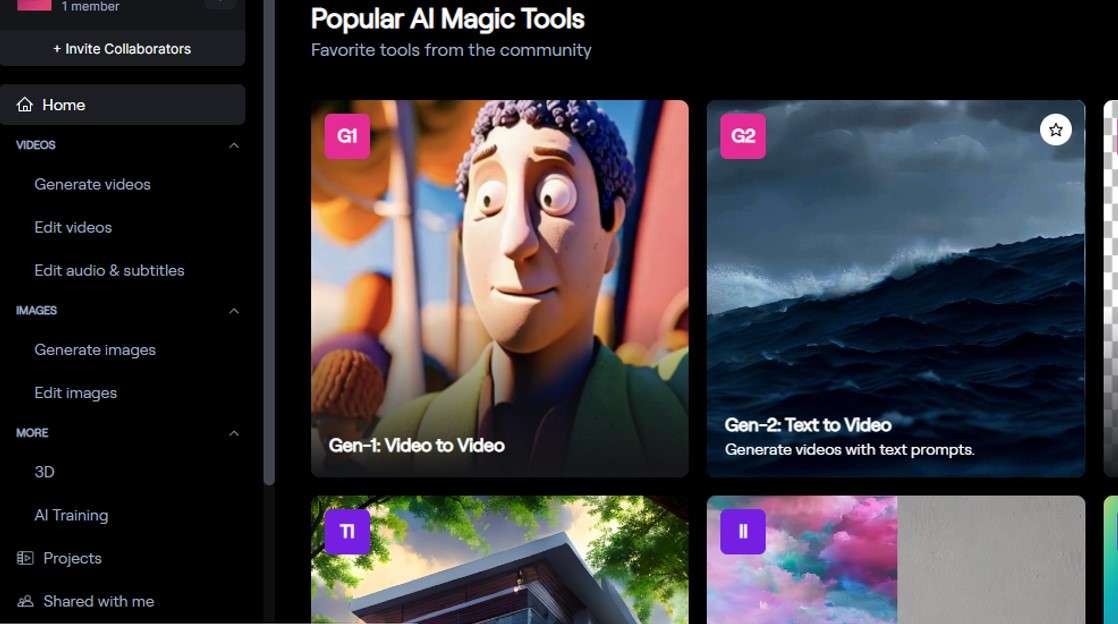
The world of Generative AI reaches another milestone with RunwayML's release of Gen-2, a multi-modal AI system capable of creating novel videos from text, images, or video clips.
Gen-2's capabilities can realistically and consistently synthesize new videos, either by applying the composition and style of an image or text prompt to the structure of a source video (Video to Video), or via text prompts (Text to Video).
[embed]https://youtu.be/BpoOVEEDiFA[/embed]
Gen-2's features also include the ability to transfer the style of any image or prompt to every frame of your video (Stylization), and to turn mockups into fully stylized and animated renders (Storyboard). Users can isolate a video and modify it with text prompts (Mask). Users can also turn untextured renders into realistic outputs by applying an input image or prompt (Render).
For those seeking even higher fidelity results, Gen-2 allows for customization of the model (Customization), to leverage the full power of the Generative AI system.
Based on user studies, the results from Gen-2 are better received over existing methods for image-to-image and video-to-video translation. It outperforms Stable Diffusion 1.5 with a preference rate of 73.53% and Text2Live at 88.24%.