AI Benchmarks Face 'Statistical Precipice'

Pierluca D'Oro of Programma Labs critiques AI benchmarking, highlighting issues with 'replay agents' and deterministic environments, and advocating for more robust, diverse, and accurately measured evaluations.

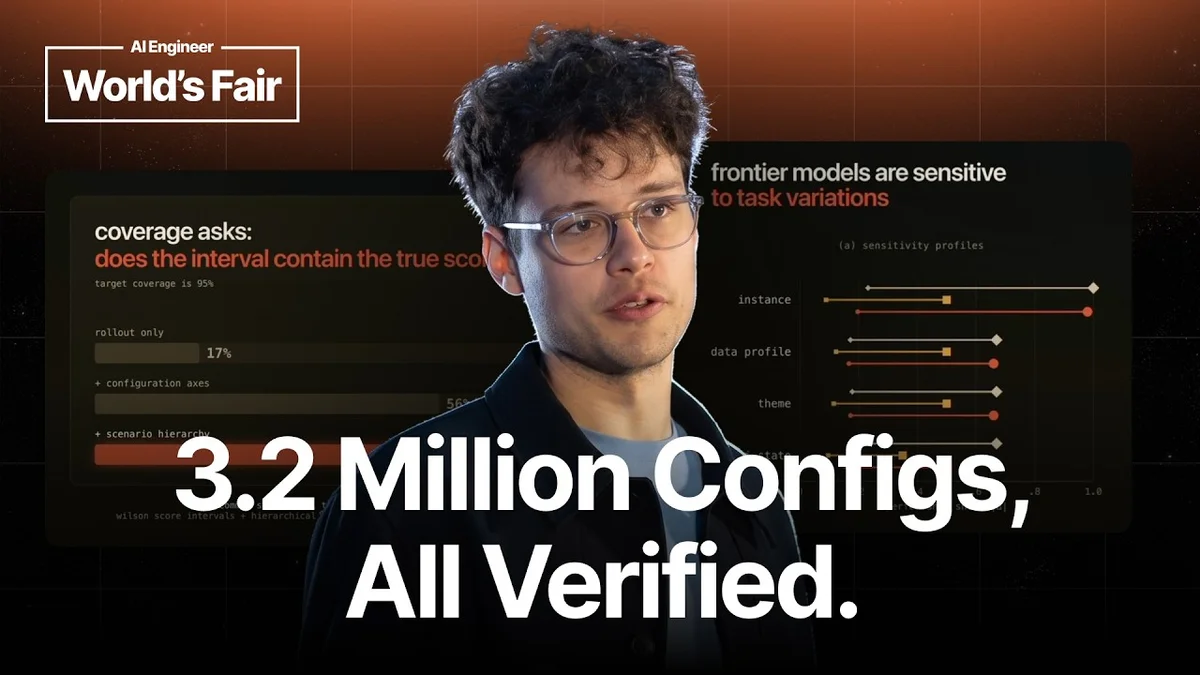
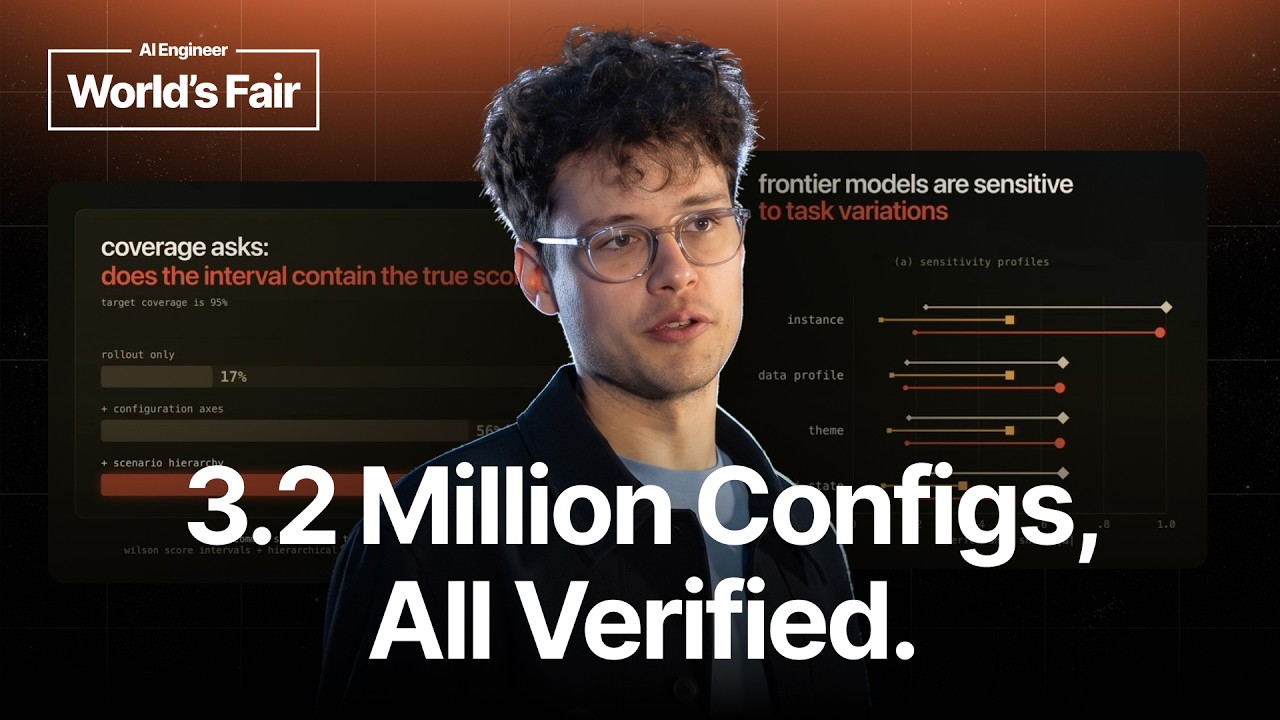
Pierluca D'Oro speaking at a podium at the AI Engineer World's Fair.
AI Engineer
Visual TL;DR
Deterministic EnvironmentsDriver
benchmarks like OSWorld or MobileWorld are easily gamed by replay agents
From the article 6 mentionsD’Oro specifically called out the 'pass@k' metric, stating that on deterministic environments, it effectively becomes a measure of the replay agent's success, rewarding search budget over genuine capability.
Programma Labs CritiqueCore
From the articlePierluca D'Oro, founder of Programma Labs, delivered a critical assessment of current AI agent evaluation methodologies, highlighting significant flaws that can lead to misleading results.
AI Benchmarks FlawedDriver
current evaluation methods lead to misleading results for AI agents
From the article 9+ mentionsThis accuracy is vital for making sound deployment decisions, as flawed confidence intervals can lead to costly mistakes.
'Replay Agent' ProblemContext
simple scripts mimic successful action sequences on deterministic benchmarks
From the article 5 mentionsThese issues point to two core problems in AI agent benchmarks: the environments themselves and the evaluation metrics.
Outperform Sophisticated AIOutcome
replay agents achieve same or better success rates than frontier models
From the articleHe demonstrated how such agents can outperform sophisticated AI models on deterministic benchmarks, a phenomenon he argues is unacceptable.
Need Robust EvaluationEffect
advocating for more diverse, verifiable, and accurately measured AI evaluations
PRISM PrinciplesContext
proposed framework for addressing benchmark flaws and improving rigor
From the article 2 mentionsD’Oro proposed a set of 'PRISM' principles for designing more robust and trustworthy environments:
Contents(4)

Pierluca D'Oro, founder of Programma Labs, delivered a critical assessment of current AI agent evaluation methodologies, highlighting significant flaws that can lead to misleading results. Speaking at the AI Engineer World's Fair, D’Oro introduced the concept of a 'replay agent', a simple script that mimics successful action sequences from a benchmark. He demonstrated how such agents can outperform sophisticated AI models on deterministic benchmarks, a phenomenon he argues is unacceptable.

AI Benchmarks Face 'Statistical Precipice' - AI Engineer
AI Benchmarks Face 'Statistical Precipice', AI Engineer

The 'Replay Agent' Problem

D’Oro explained that a replay agent is created by recording successful trajectories of a frontier model on a given task. This recorded sequence of actions, such as tapping or typing, is then replayed blindly for each task. For benchmarks with hundreds of tasks, this results in a script less than a megabyte in size. When evaluated on standard benchmarks like OSWorld or MobileWorld, these replay agents often achieve the same or even better success rates than the original frontier models. This occurs because many current benchmarks are static and deterministic, making them easily 'gameable' by this strategy. D’Oro specifically called out the 'pass@k' metric, stating that on deterministic environments, it effectively becomes a measure of the replay agent's success, rewarding search budget over genuine capability.

Addressing Benchmark Flaws: PRISM Principles

These issues point to two core problems in AI agent benchmarks: the environments themselves and the evaluation metrics. D’Oro proposed a set of 'PRISM' principles for designing more robust and trustworthy environments:

  • Privileged: Ensure success is graded against real internal states.
  • Realistic: Reproduce real-world app appearances, interactions, and complexity.
  • Integrity-checked: Verify that every task is feasible, coherent, and non-trivial.
  • Sandboxed: Maintain self-contained environments with deterministic resets.
  • Multifactorial: Introduce variations along axes like data, appearance, and state.

D’Oro noted that while some existing benchmarks address certain aspects well, no single benchmark currently unifies all these principles. His team developed DGWorld, a benchmark composed of 15 sandboxed Android mobile apps spanning 7 real-world domains. DGWorld features 387 verified scenarios and over 3.2 million checked configurations, ensuring diversity and validity across various parameters such as instance values, data profiles, themes, and starting screens.

The Importance of Verifiable Diversity and Accurate Metrics

The key to scaling diversity in benchmarks, D’Oro emphasized, lies in having a robust verification strategy. His team implemented a system akin to a compiler that takes parameterized task templates, resolves placeholders against a profile database, checks constraints (like entity counts and balances), and filters tasks to ensure they are true at reset. This process generates valid configurations before an agent ever interacts with them.

D’Oro also highlighted the critical need for honest uncertainty measurement. He explained that while agent action stochasticity is often considered, environmental variability (from different apps, scenarios, data, themes, or starting screens) is equally important. A proper methodology must capture both. He demonstrated how standard statistical techniques often underestimate uncertainty, leading to overconfident evaluations. For instance, a 95% confidence interval based solely on rollouts might only have 17-20% coverage, whereas incorporating environmental variation and scenario hierarchy can improve this to 95%. This accuracy is vital for making sound deployment decisions, as flawed confidence intervals can lead to costly mistakes.

A Call for Rigorous Evaluation

D’Oro concluded with a strong call for rigor in AI benchmarking, stating, “a non-rigorous benchmark is misleading for the field, and it is misleading for your own decisions.” He urged the AI community to move beyond benchmarks that can be easily gamed or lack proper error bars, emphasizing that honesty and rigor in evaluation are paramount for making informed decisions and driving genuine progress.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.