The performance ceiling for large language models (LLMs) in production is not merely about raw model size, but rather the efficiency with which diverse, high-volume inference requests can be managed. Traditional load balancing approaches, simple round-robin distribution, fail catastrophically when confronted with the heterogeneous nature of modern AI workloads, leading to system congestion and unacceptable end-user experience. This fundamental challenge is what spurred the creation of LLM-D, an open-source project that introduces intelligent, distributed routing to the LLM inference stack.
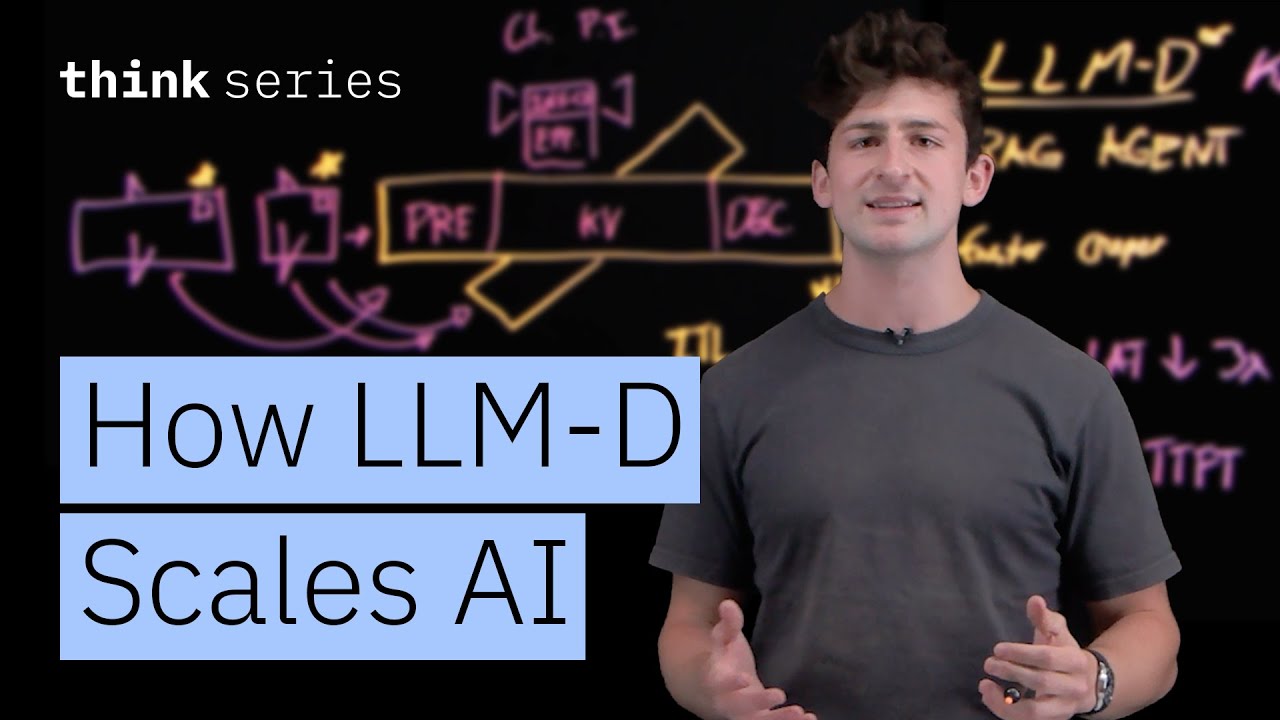
Cedric Clyburn, Sr. Developer Advocate at Red Hat, detailed the architecture and performance gains of LLM-D in a recent presentation, explaining how it leverages foundational technologies like Retrieval-Augmented Generation (RAG) and Kubernetes to redefine scalable AI infrastructure. The core insight driving LLM-D is that not all LLM requests are created equal, and treating them uniformly results in massive inefficiencies in hardware utilization and latency.
Consider the reality of production environments where requests range from small, context-heavy RAG queries to complex, multi-step agentic workflows, such as AI-assisted coding. When these disparate workloads hit a standard inference server, they create bottlenecks. The presenter illustrated this inefficiency using the analogy of an airport without air traffic control, where small domestic planes and large international jets attempt to use the same runway without coordination. This leads directly to high "inter-token latency" (ITL), the time it takes for a request to be processed and its response generated, negatively impacting the user experience.
LLM-D addresses this by implementing a highly sophisticated inference gateway that acts as an intelligent traffic controller. This gateway evaluates incoming prompt requests and intelligently routes them based on several metrics, ensuring that workloads are matched to the optimal hardware and processing path.
The Endpoint Picker (EPP) at the heart of the system assesses the current load, predicts latency, and determines the likelihood of data already being cached within the system. This predictive routing capability is crucial for meeting stringent Service Level Objectives (SLOs) and maintaining Quality of Service (QoS) agreements, particularly in mission-critical applications where milliseconds matter.