Cristóbal Valenzuela told AI Engineer that Runway now generates video so real he cannot tell it from reality and is turning that engine into a real-time operating system.
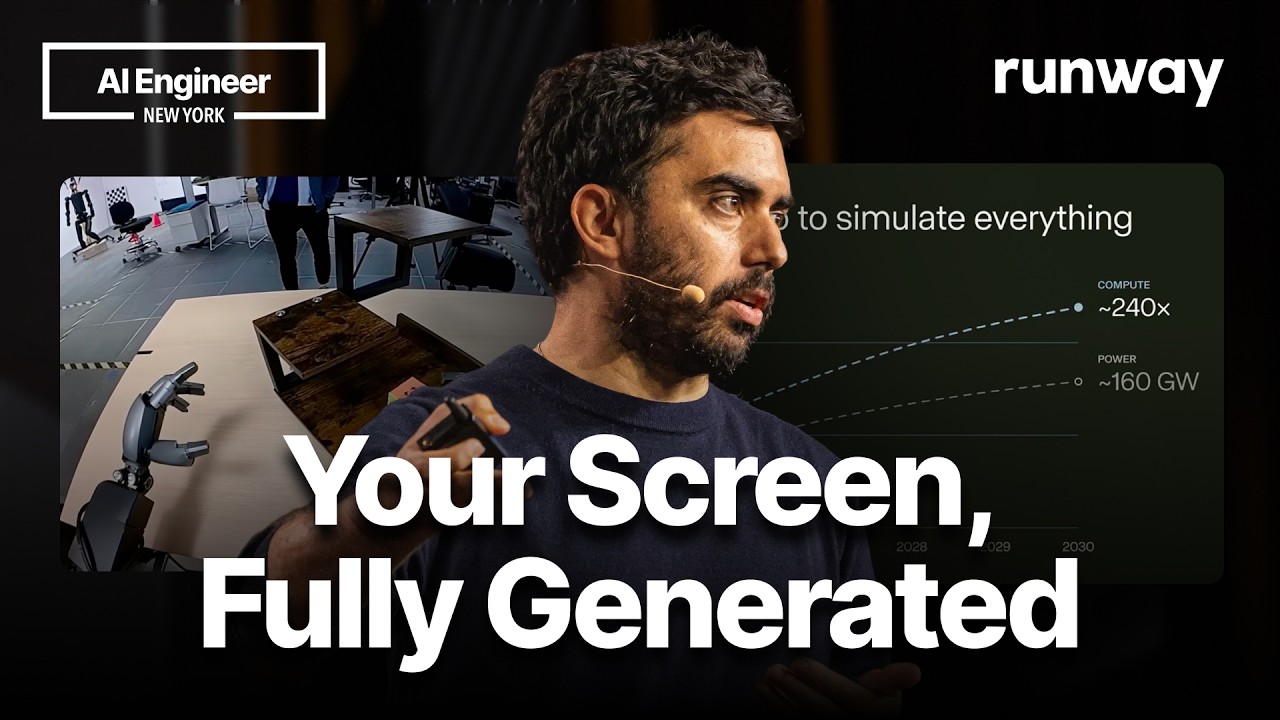
The demo matters now because the models have crossed a human discrimination threshold. Valenzuela said Runway has measured whether people can distinguish real and generated video and that test is passed, which shifts the problem from making pretty clips to building interactive world simulators that learn physics from pixels.
It started with an orange. In 2019 Runway made a 128 by 128 pixel model that rendered an orange falling from a tree and walking, upsampled to watchable resolution. Today the same next-frame prediction idea, scaled with much larger networks and much more compute, produces fully synthetic characters and locations at high fidelity. Valenzuela argued the progress follows scaling laws for video, not just language, and that larger models acquire physics, object permanence, gravity, occlusion and motion without hand-coded rules.
That last part is the pivot. Valenzuela said he looks at current outputs after ten years in the field and still cannot call real versus fake, and the company now evaluates models on physics and geometry, not just preference scores. The same next-frame predictor becomes a simulation engine when run fast enough in a loop.
Runway showed what that loop enables when it is interactive. A single image becomes a world interface model with no Unity, Unreal or Blender underneath, where clicks turn car lights on, spin the vehicle or open the hood and the model predicts consistent next frames. The lab is extending the idea to Continuum, a system that streams the screen from a video model. Valenzuela demoed portals that turn highlighted text about San Francisco fog, batteries or photosynthesis into live, resizable 3D visualizations, plus visual thinking where a coding agent spins up a Continuum instance to reason through a problem like a 3D bike model, and a reactive Mars outpost generated from search intent.
The work is still early research and Valenzuela said the team does not yet know what to call these interactions. They are not video, not visualization, not game. Runway plans to release most of what was shown for general use in the next 8 to 12 months.